Real Estate Lead Analytics
From a messy CRM-style lead export to marketing ROI and a prioritized call list — a full data-engineering-to-analysis pipeline, built on privacy-safe synthetic data.
Overview
Real-estate acquisition pipelines produce large, messy lead files — inconsistent statuses, hundreds of campaign-coded list names, dollar values stored as text, duplicates, and heavy missingness. The data has to be engineered into shape before it can guide where marketing dollars go.
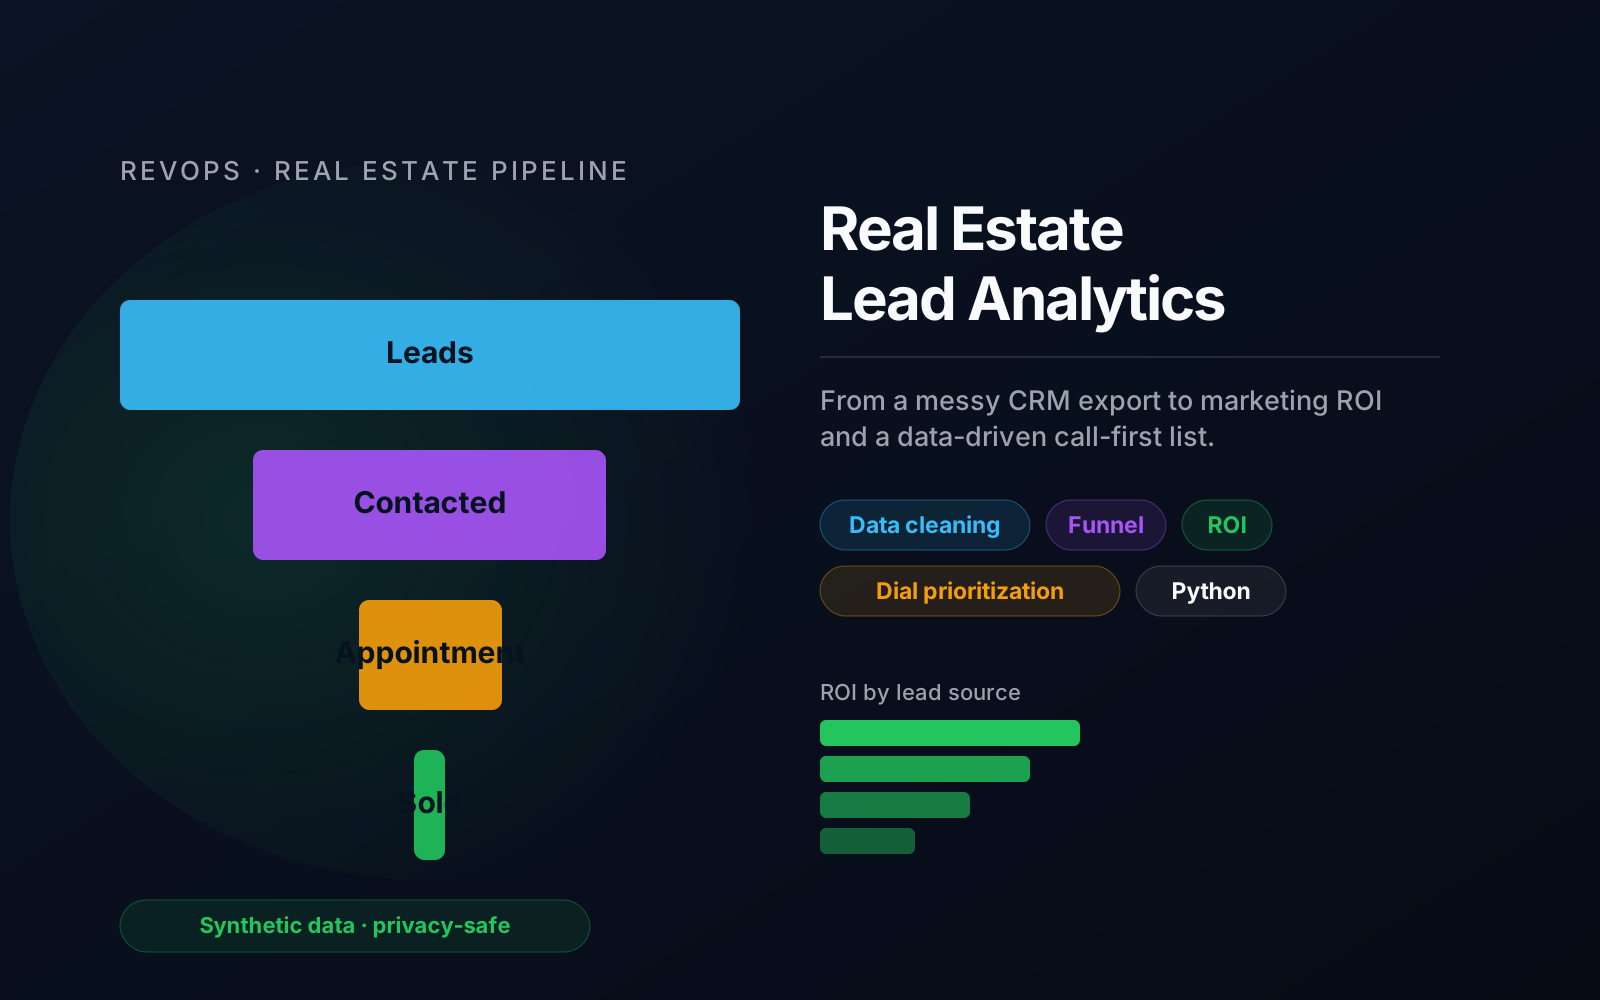
A documented pipeline showing where the funnel leaks (earliest at contact), which sources return the most per dollar (cheaper High-Equity and Absentee lists beat pricier distress lists), and which leads to dial first. All results are illustrative of the method on synthetic data, not real business figures.
Method used.
- Generated a fully synthetic dataset mirroring the statistical shape of a real pipeline (county mix, value quartiles, phone quality) so no private or personal data is ever exposed.
- Built a reproducible cleaning stage: de-duplication, parsing dollar/percent strings, collapsing 28 status spellings into a canonical funnel, and recovering 1,400+ list names into six source families — every fix logged.
- Analyzed funnel drop-off, marketing ROI and cost-per-deal by lead source, conversion by county, and contact-data quality — then tiered leads into a call-first dial list.